Your ad chose the denominator
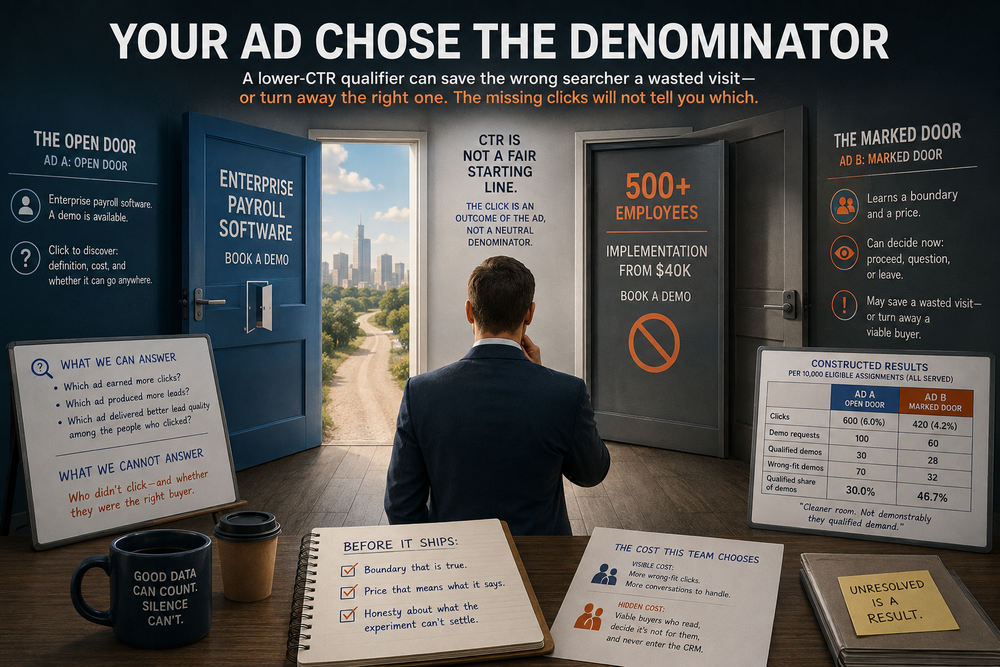
A lower-CTR qualifier can save the wrong searcher a wasted visit—or turn away the right one. The missing clicks will not tell you which.
At 4:42 Friday, a creative test has achieved a corporate miracle: everyone is right and nobody has a decision.
The media buyer points out that CTR fell 30%. Sales points out that wrong-fit demos fell by more than half. Demand gen points to a prettier qualified-demo share. RevOps, who has been quiet in the manner of someone about to spoil lunch, notes that the qualifying ad produced two fewer qualified demos.
The experiment ends today. Which ad ships?
In the constructed comparison, 10,000 eligible search opportunities were randomly assigned to each arm and every assignment produced an impression. Query targeting, bids, landing page, offer, CTA, and other assets stayed fixed; only pinned Description 1 changed.
Ad A: the open door
Enterprise Payroll Software | Book a Demo
example.com/enterprise-payroll
Built for complex teams. Automate payroll, tax, and reporting across your organization.
The searcher learns: This is enterprise payroll software. A demo is available.
The searcher must spend a click to discover: what “enterprise” means here, what implementation costs, and whether the conversation can go anywhere.
Ad B: the marked door
Enterprise Payroll Software | Book a Demo
example.com/enterprise-payroll
500+ employees. Implementation from $40K. Automate payroll, tax, and reporting.
The searcher learns: The company appears to require at least 500 employees, and something called implementation begins at $40,000.
The searcher can decide now: “This may be for us,” “I need to understand that price,” or “Nope.”
Ad B has moved part of the landing page into the auction. It can help an enterprise buyer recognize herself. It can save a 40-person company from opening a tab that was always going to disappoint.
It can also be a terrible ad. Perhaps 500 employees is not a real boundary. Perhaps a fast-growing 430-person company has exactly the multi-entity payroll mess the product solves. And “implementation from $40K” still leaves a serious noun missing: is that a one-time services fee, first-year cost, or software price? The ad may be qualifying demand. It may merely be scowling at the search results.
Responsive search ads assemble assets in different combinations and orders. If the qualifier is the treatment, it has to be present; Google says required text should be pinned to Headline 1, Headline 2, or Description 1. Pinning costs combinatorial freedom; it fixes the qualifier in Description 1.
The ad chose who clicked
CTR is clicks divided by impressions. The formula is innocent. The trouble begins when the team calculates “lead quality” among form submitters and treats that survivor group as a neutral starting point.
It is not neutral. The ad helped choose it.
Evaluating creative only among its clickers or leads is like evaluating two nightclub door policies by interviewing whoever each bouncer admitted. An ad that produces one lead and qualifies that lead can report 100% lead quality. This is excellent news if the business can live on one lead.
The click is an outcome of the ad, not a fair denominator for judging it.
Return both ads to a common starting population. In this construction, “qualified” was defined before launch as a buyer with enterprise payroll complexity, budget for the one-time implementation and separate software, authority, and a credible buying window. Headcount was a useful fit signal, not a hard rule.
The business also named the bargain before launch: the qualifier had to cut wrong-fit demos at least in half without reducing qualified demos by more than 10%.
| Outcome from 10,000 randomized assignments per arm, all served | Ad A: open door | Ad B: marked door |
|---|---|---|
| Clicks | 600 (6.0% CTR) | 420 (4.2% CTR) |
| Demo requests | 100 | 60 |
| Qualified demos | 30 | 28 |
| Wrong-fit demos | 70 | 32 |
| Qualified share of demos | 30.0% | 46.7% |
Ad B's qualified share looks wonderful: 46.7% versus 30.0%. Put that result on a slide and it will grow a green arrow before the meeting begins.
But from the common starting population, qualified demos slipped from 30 to 28 while wrong-fit demos fell from 70 to 32. Ad B produced a cleaner room, not demonstrably more qualified demand.
On the observed counts, Ad B passes the rule: its qualified-demo loss is 6.7%, apparently inside the 10% limit by one demo. But 28 versus 30 is too little evidence to know whether the long-run loss is actually within that limit. Ten percent of Ad A's 30 is three; Ad B is two down. One late qualification or changed CRM classification consumes even the visible cushion.
This does not prove Ad B's long-run loss exceeds 10%. It means the comparison has not separated the acceptable side from the unacceptable one. The table establishes that traffic composition changed, not that the treatment preserved enough viable demand.
Then the people at the edge read the ad.
The price confused. The boundary did not.
Put both ads, without a landing page, in front of people who resemble in-scope and near-boundary buyers. Do not ask which one they like. Ask them to say what the company sells, whom it serves, what the $40,000 buys, and what they would do next.
In this constructed readout, enterprise buyers agreed only that at least $40,000 was involved. Some heard a one-time services fee; others heard a first-year or software price. The price failed its readback.
The headcount rule did not. Near-boundary buyers understood “500+” perfectly. One was a VP running multi-entity payroll for 430 employees, with budget for both charges, buying authority, and an active replacement project. She did not say, “I am confused.” She said, “They are not for us.”
Sales' prewritten rule called her qualified. The company's best customers often had more than 500 employees, but implementation did not require it. The company had turned a pattern among its best customers into a lock on the door.
The headcount result is not a comprehension failure. It is successful delivery of an indefensible rule.
Direct customer evidence does not merely validate clarity. Sometimes it proves that the words work exactly as written—and that this is the problem. More sample would estimate the effect of “500+” more precisely. No amount of sample can turn a preference into a service limit the business will not honor.
What the live test can answer
The CRM can count the people who enter its room. Outside the marked door, a wrong-fit searcher, a viable prospect, a distracted person, a comparison shopper, and a robot with excellent taste in payroll software all leave the same record: nothing.
Silence cannot testify.
The table gave both ads a visible common starting line: 10,000 randomized assignments per arm, all served. A live account hides that line. Some people assigned to an arm may never be served, and Google Ads does not hand you an “eligible assignments” column.
Random assignment is still the bridge. The Ad A-versus-Ad B test stops this Friday. It is not edited in place. After the revised sentence passes direct readback, the team starts a new Search custom experiment, with Ad A as the original and the revised description as the treatment. The team uses a 50/50 traffic-and-budget split and Google's recommended cookie-based assignment so one buyer stays in one arm. Only the pinned description changes. Bids, targeting, landing page, conversion goal, and other assets remain fixed; drift would change the question.
Follow one possible buyer. Google's split assigns her to an arm. The auction may never serve her. If it does, the revised sentence may stop her at the marked door. No click means no form. No form means no CRM record. Every system downstream of the ad reports nothing. The team cannot tell whether it spared a wrong-fit searcher a wasted visit or lost a viable buyer.
At the arm level, her disappearance adds nothing to the Qualified lead conversion total. That is exactly why the team must not shrink the comparison to the people who clicked. Google Ads does not expose the eligible-assignment count, so the team cannot reproduce the table's per-10,000 rate. What it can observe is the actual Qualified lead conversion total for each arm. The randomized 50/50 split supplies the common starting line that the missing assignment column cannot display: compare the mature treatment total with the mature original total.
That arm-level comparison includes the whole campaign version as Google Ads delivers it, including post-assignment differences in whether the ad was served. Dividing by impressions, clicks, or forms would condition on a gate the version itself can change.
Here, Qualified lead is the team's pre-defined qualified-demo outcome under Google Ads' system name. The CRM sends that eventual decision back as a distinct conversion action—Google provides an offline Qualified lead goal. “Conversions” means that action, not form fills, in both arms. If its definition or import changes, the outcome has changed beneath the experiment.
The auction test and the direct read are two witnesses. Ask one question of each. The direct read: what did shown buyers understand? The auction test: how did the mature Qualified lead totals differ by arm? The direct read cannot measure the whole campaign version's effect. The arm totals cannot show that a searcher read the qualifier and left. Neither can interview a vanished click.
The new experiment has two finish lines. Google reaches the first when traffic allocation stops. The team reaches the second only when the outcomes mature. The final Tuesday lead may still be moving through Sales toward a CRM qualification weeks later, so the team waits until each arm's last cohort has received the same full qualification window.
Mature is not the same as resolved. Only after that second finish line can the team read the treatment-versus-original Qualified lead totals, and even then they may not answer the 10% question. Qualified demand can be so rare that the business around the experiment changes before enough of it arrives, leaving the old and new traffic to answer different questions.
“Unresolved” is a result.
It means this experiment did not distinguish an acceptable qualified-demand loss from an unacceptable one under a stable, mature comparison. It does not mean the next decimal place should choose the ad.
The cost this team chooses
Ad B does not ship. Its headcount boundary is false, its price is incomplete, and the qualified-demand result is unresolved.
The next treatment says only what the business will defend:
Enterprise Payroll Software | Book a Demo
example.com/enterprise-payroll
One-time implementation from $40K; software extra. For multi-entity payroll teams.
Now $40,000 names a one-time implementation floor, not an unspecified pile of money, and the buyer knows software is additional. Multi-entity complexity describes the problem without disguising a customer pattern as a prohibition. Before the live test, in-scope and near-boundary buyers have to read those meanings back from the ad itself. If they hear “$40K total” or “500 employees minimum,” the sentence is not ready.
Friday ends the old test, not the question. Ad A becomes the control for a new 50/50 experiment; once the revised sentence passes the direct read, the revised treatment receives the other half. The visible cost is annoying: more wrong-fit clicks and more conversations Sales may reject while the evidence matures. This business can absorb that burden. It will not accept a full rollout whose possible cost is invisible.
If the mature evidence shows both prewritten limits were met—wrong-fit demos down at least half, qualified demos down no more than 10%—before the context changes, the revised arm earns the account. If the evidence still leaves either limit unresolved, the open door stays—not because Ad A won, but because its burden arrives in a queue the business can see and carry.
That judgment belongs to this business. If 500 employees were a genuine implementation floor, the verdict could reverse: Ad B would be an honest service notice, and lower CTR might be the expected cost of telling the truth early. The team would still need evidence that demand above the real floor survived. “We meant to repel people” would still prove nothing by itself.
An ad owes the wrong person enough truth to leave. It owes the possible right person no less: a boundary that is true, a price that means what it says, and honesty about what the experiment never managed to settle. Without those, a viable buyer may obey the ad, disappear, and never enter the CRM.