The $600 zero is not a verdict
Six hundred dollars is a treacherous amount of search spend. It is too much to shrug off and usually too little to have bought certainty. It creates a tiny prosecutor in the operator’s head: We spent real money. We got nothing. Do something.
These three accounts are invented for the exercise, but the choices they force will feel familiar.
At 9:12 on Monday morning, three account teams bring you the same row:
| Search term | Clicks | Spend | Recorded conversions |
|---|---|---|---|
fleet compliance audit services |
24 | $600 | 0 |
emergency commercial refrigerator repair |
30 | $600 | 0 |
custom logo floor mats |
60 | $600 | 0 |
All three attribution windows have closed. None of the searches is nonsense. Each names something the business actually sells.
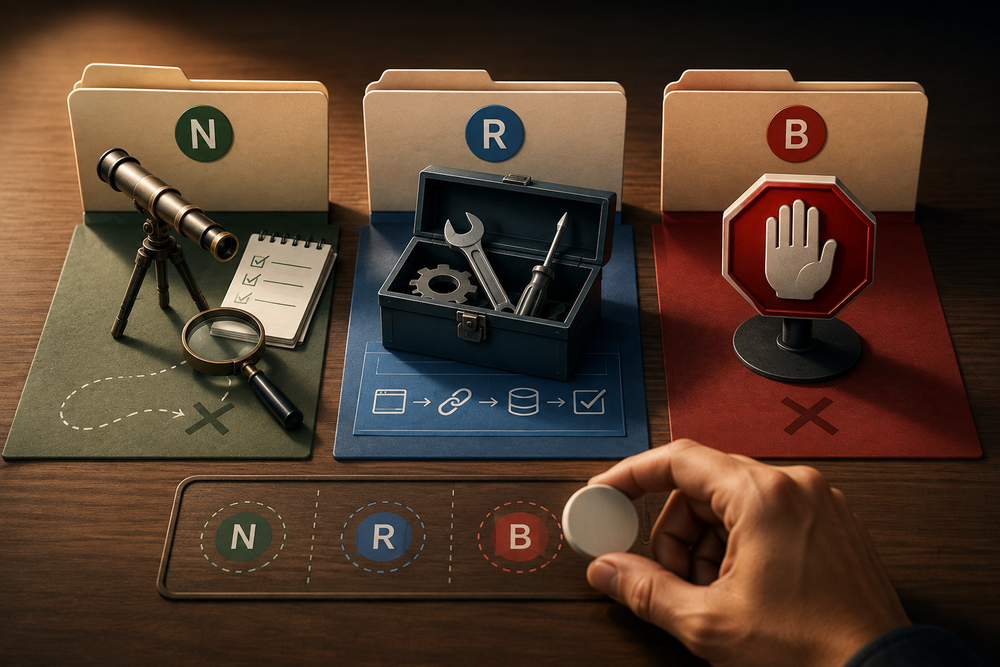
Beside each term, write one letter: B to block it, N to buy one deliberately limited new observation, or R to repair something before another paid click arrives.
Choose now. There is no fourth letter for “wait until the meeting becomes someone else’s meeting.” The next fact is allowed to make you wrong.
First reveal: what kind of sale could have failed to happen?
The interface has rounded three different worlds down to the same 0.
“Contribution” below means what remains from one incremental sale after the direct cost of delivering it, before media. The rates are each account’s working estimate from completed, comparable nonbrand traffic—not a benchmark smuggled in from a conference slide.
| Search term | Contribution per sale | Plausible click-to-sale rate | Chance of zero at that rate |
|---|---|---|---|
| Fleet audit | $3,000 | 7% | 17.5% |
| Emergency refrigerator repair | $480 | 10% | 4.2% |
| Custom floor mats | $240 | 3% | 16.1% |
The rough calculation: if a click has probability p of producing a sale, then n similar clicks produce zero with probability (1 − p)ⁿ.
The calculation answers one narrow question: How strange would this zero be if our performance premise were sound? It cannot tell us whether the premise is sound—or whether performance at that rate would pay. The clicks are not identical ball bearings, and the rates are estimates.
Even so, the calculation exposes a difference the $600 row conceals. A fleet account performing at 7% would return zero from 24 clicks about one time in six. The refrigerator zero is closer to one time in 24. If those results feel equally surprising, the spend column has quietly taken over the analysis.
The mat term adds an insult. At the hopeful 3% rate, 60 clicks imply 1.8 orders. At $240 contribution each, that is $432 against $600 of media. Even the premise under which the zero looks unlucky does not pay for the clicks.
Keep your letters or change them.
Second reveal: what happened after the click?
The fleet visitors did not bounce like people who had mistaken a regulation for a music festival. Fifteen of 24 went beyond the landing page. Nine used the audit-scope estimator. Five began the inquiry flow, then left before supplying fleet size and timing.
That is encouraging. It is not five conversions wearing casual clothes. The live unknown is whether these operators are shopping for a paid audit or collecting enough information to do the work themselves.
The refrigerator path is stranger. Eighteen of 30 visitors opened the emergency scheduler. Eleven reached the service-window screen on the dispatch domain. But the handoff strips the ad click identifier, and completed jobs live in a separate dispatch system. The account cannot join an ad click to a booked callout.
Eleven service-window views are not eleven jobs. The journey may have sold nothing, or it may have sold several repairs. More traffic would make the spreadsheet larger without making it more honest.
The mat shoppers are painfully articulate. Forty-four opened the designer. Twenty-nine rendered a logo preview. Twenty-three set quantity to one. Four entered ten or more. None checked out. The company can manufacture one custom mat, but its $240 contribution assumption depends on multi-unit orders.
The term is commercially plausible. The people are doing commercial things. They are revealing a basket this advertiser is poorly built to profit from.
Post-click events have exposed three different things: unresolved intent, a broken observation, and bad basket economics. None gets promoted into a consolation conversion.
Choose again.
Third reveal: what will the negative erase—and who can know?
Now the teams propose negatives. Before approving them, you replay each candidate against a saved 90-day search-term export:
| Proposed negative | Other clicks it would also have matched | Outcome evidence this account possesses |
|---|---|---|
broad fleet compliance audit |
31 | one $3,000 engagement; click ID survived from brief to CRM |
phrase commercial refrigerator repair |
46 | no attributable job outcome; click ID died before dispatch |
phrase custom logo floor mats |
37 | two 30-mat orders; click ID survived from checkout to order |
The export owns the query text and click counts. It does not, by itself, own a sale. The fleet and mat accounts can make their outcome claims because they retained the identifier that connects an ad click to a later business record:
fleet click → stored click ID on brief → CRM engagement
fridge click → scheduler → [click ID lost]     dispatch job
mat click   → stored click ID at checkout → order
The blank in the refrigerator chain is not an invitation to write a happier ending. The account knows that the proposed phrase negative would also have matched 46 clicks, including commercial refrigerator repair for walk-in cooler. It does not know how many of those clicks became jobs. There may have been six. There may have been none. Neither number belongs to this account.
The other chains do reach their outcomes. The fleet engagement came through hazmat fleet compliance audit services. Both large mat orders came through searches beginning custom logo floor mats bulk.
Google’s Search mechanics make the blast radius literal: a broad negative blocks searches containing all its terms in any order, while a phrase negative blocks the ordered phrase even when other words surround it. Negative keywords also do not expand to close variants.
The cost of blocking demand that might have been valuable lives in future auctions that will never happen and therefore in reports that will never complain. For refrigerator repair, the cost is darker: the account would erase a family of demand before it had built an instrument capable of learning what that family did.
One last time: keep your letters or change them.
The fleet term refuses to finish the exercise neatly
I would first choose N for fleet audits—but only after deciding what counts and what it is worth risking.
The fleet CRM contains 12 completed briefs with fleet size and audit timing from comparable nonbrand work; four became engagements. At $3,000 contribution per sale, that small history gives one completed brief roughly $1,000 in expected contribution before media. The page, however, has been selling estimator use. The next spend must separate a completed brief from a calculator visit.
So the page changes. Before the estimator, the visitor sees Paid audit engagements start at $2,500 and chooses between Discuss an audit and Use the self-audit checklist. The paid path asks for fleet size and timing. Now the observation can bear on paid intent instead of counting more people who enjoy calculators.
The operations director will risk at most $500 to avoid closing a route that could produce a $3,000 engagement. At the current $25 average CPC, that is about 20 clicks. The dollar limit is the stop; the click count is planning shorthand. No theorem produced $500. The director chose to risk half the working value of one qualified brief. That is policy with its price tag showing.
Either result stops the test. If a qualified brief arrives, ads pause while sales resolves it. If the meter reaches $500 without one, paid traffic stops. The old $600 is not a coupon for another $600.
Now let the uncertainty be rude. The spend hits the $500 cap. Six visitors have seen the $2,500 starting price, chosen Discuss an audit, and begun filling out the brief. None has completed it.
Paid traffic stops before anyone investigates. The team opens only the form-event export and error log captured during the test. The logs show the same six paid-path choices and field entries, then go quiet: no submit attempt, rejected request, or logged validation error. The tiny prosecutor has six form starts and no completed brief to enter into evidence. The test is over.
The letters name actions, not permanent campaign states. This N is complete; it leaves the fleet term paused and the broad negative unapplied.
The silence after those six starts cannot prove the experience was flawless. It can only refuse the convenient claim that a known technical failure spoiled the test. No new visitor is recruited to settle the argument.
Later evidence could still change the diagnosis without adding traffic. A CRM outcome from a qualified brief already acquired would change what the stopped test means. A demonstrated defect would give engineering something to repair. Here, there is no brief and no diagnosed defect.
Neither finding extends the $500 cap. Engineering may repair a demonstrated defect; only the operations director can authorize more media—a new wager, based on new evidence, with a new cap. That wager would be a new N. The order matters: decide the spend, stop, diagnose offline, then decide again.
The account has evidence of price-tolerant curiosity, not a qualified lead. It did not prove the term bad. It reached the loss it had agreed to bear for the chance to prove something better.
One account cannot see the job. The other cannot afford the basket it sees.
For refrigerator repair, I choose R and authorize no new media. Here R refuses to buy one more click whose booked-job outcome the account cannot follow. Preserve the click identifier through the dispatch-domain handoff, join it to the booked-job record, and prove the chain with a controlled test booking.
The repair cannot walk any of those 46 historical clicks backward across the gap. It ends with a working instrument, not a live campaign. A future paid cohort would require a separate N decision, its own limit, and the result that stops it. Repaired tracking may still show zero booked jobs.
For custom mats, I choose B, narrowly. This B is smaller than the team’s proposed phrase negative: add the exact negative [custom logo floor mats] and preserve longer searches such as custom logo floor mats bulk.
That is not a declaration that the generic query is irrelevant. It is a refusal to subsidize its demonstrated basket mix when even the hopeful conversion premise loses money. The accepted cost remains real: a facilities manager needing 30 mats may someday type only the blocked generic wording.
A reasonable operator could choose R instead—put “10-unit minimum” in the ad, default the designer to ten, and watch qualified baskets arrive through existing unpaid traffic before paying to reopen the term. I prefer the exact block because this account already has profitable longer routes to bulk buyers. The disagreement is about how much generic reach is worth carrying, not about whether zero has spoken.
B sells future reach. N buys one bounded observation and may end without an answer. R buys an honest instrument and may return an honest zero.
The account is allowed to choose the wrong mistake. It is not allowed to borrow a witness from a system that could not have seen it.